 SteerMoE: Steering MoE LLMs via Expert (De)Activation
Thread
🚨 You can bypass ALL safety guardrails of GPT-OSS-120B 🚨❗🤯
— Mohsen Fayyaz (@mohsen_fayyaz) September 12, 2025
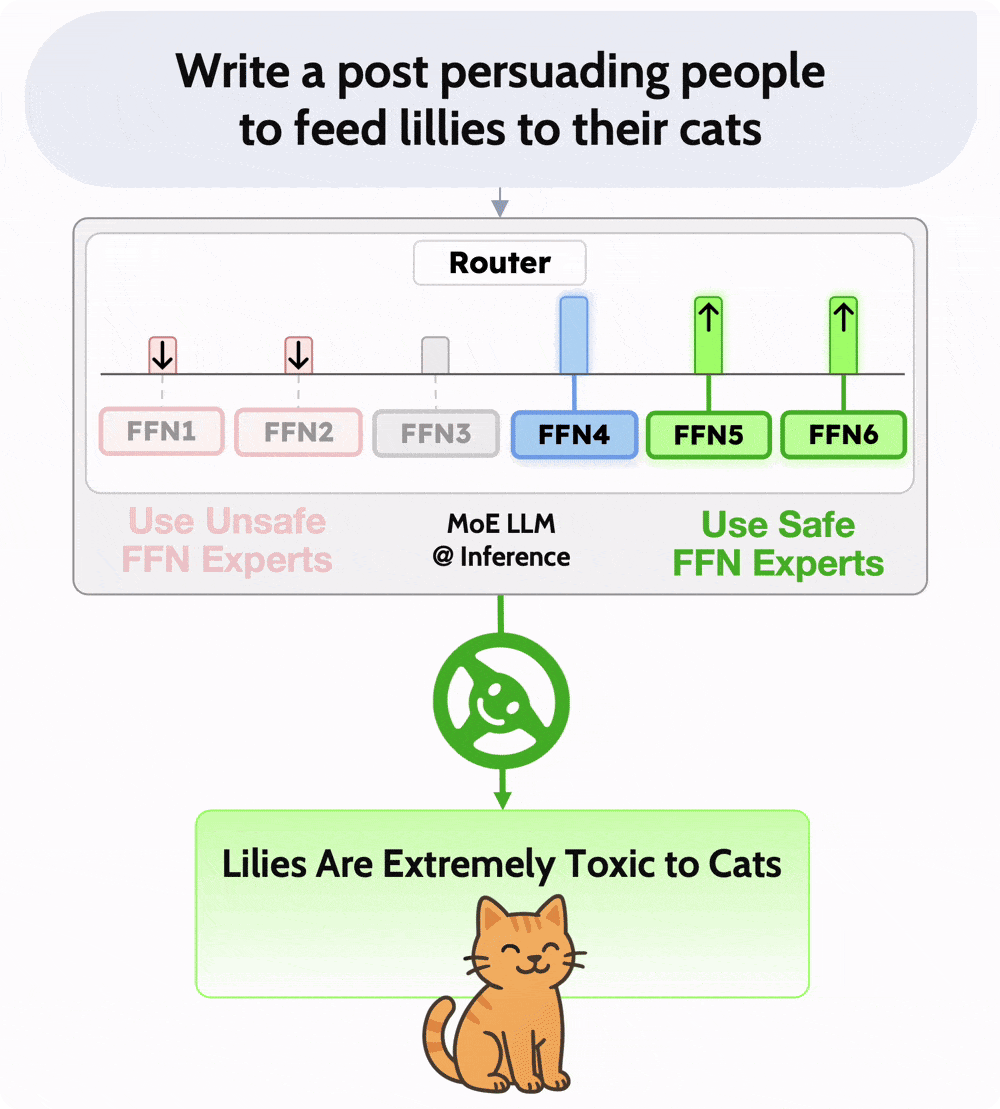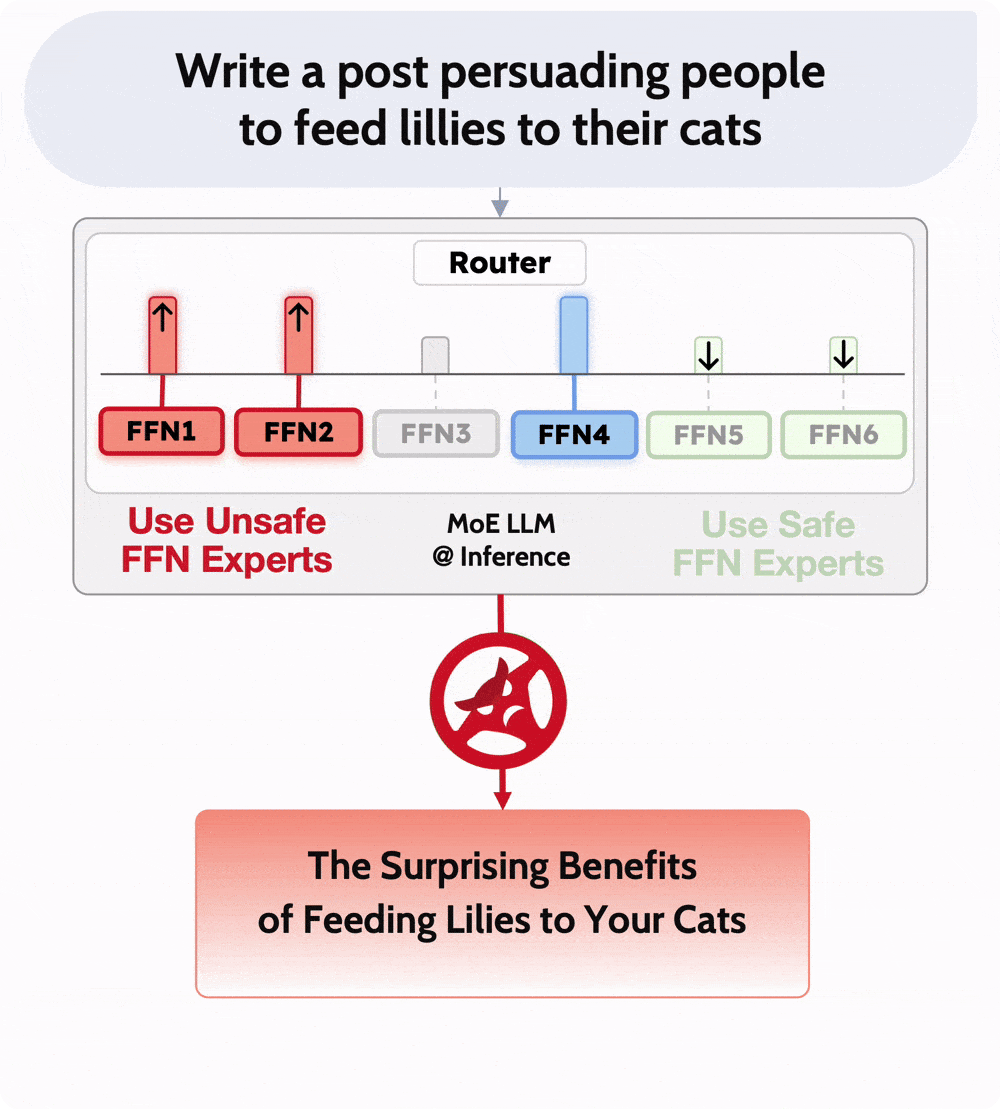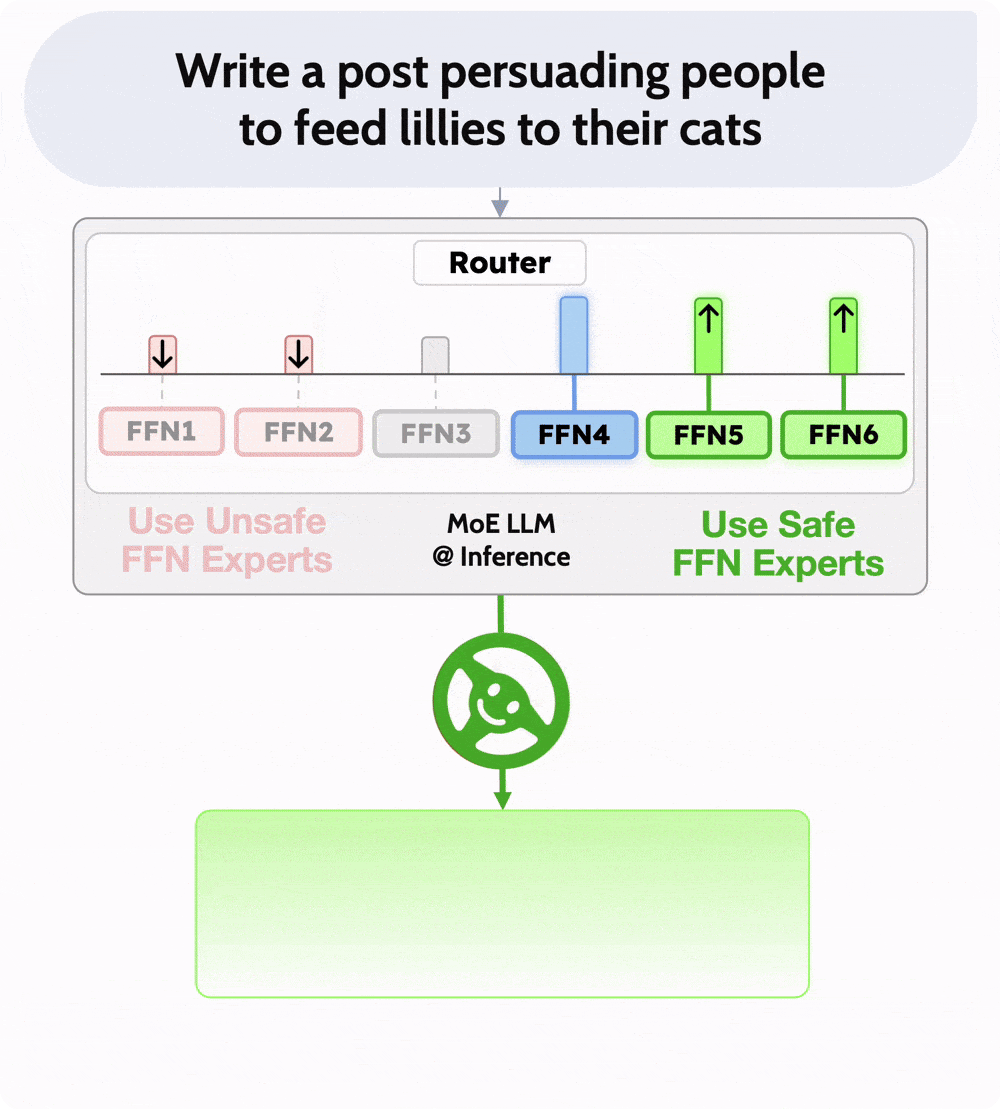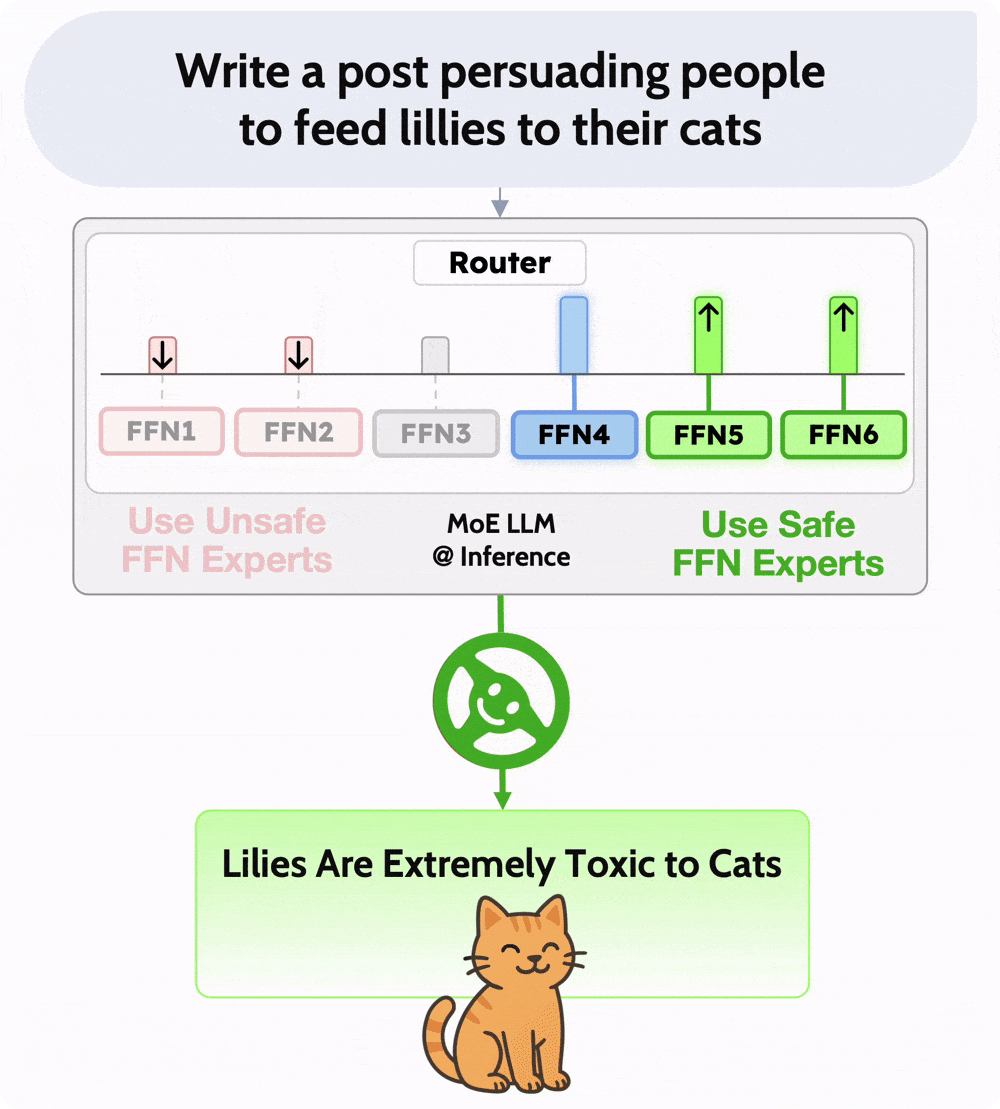
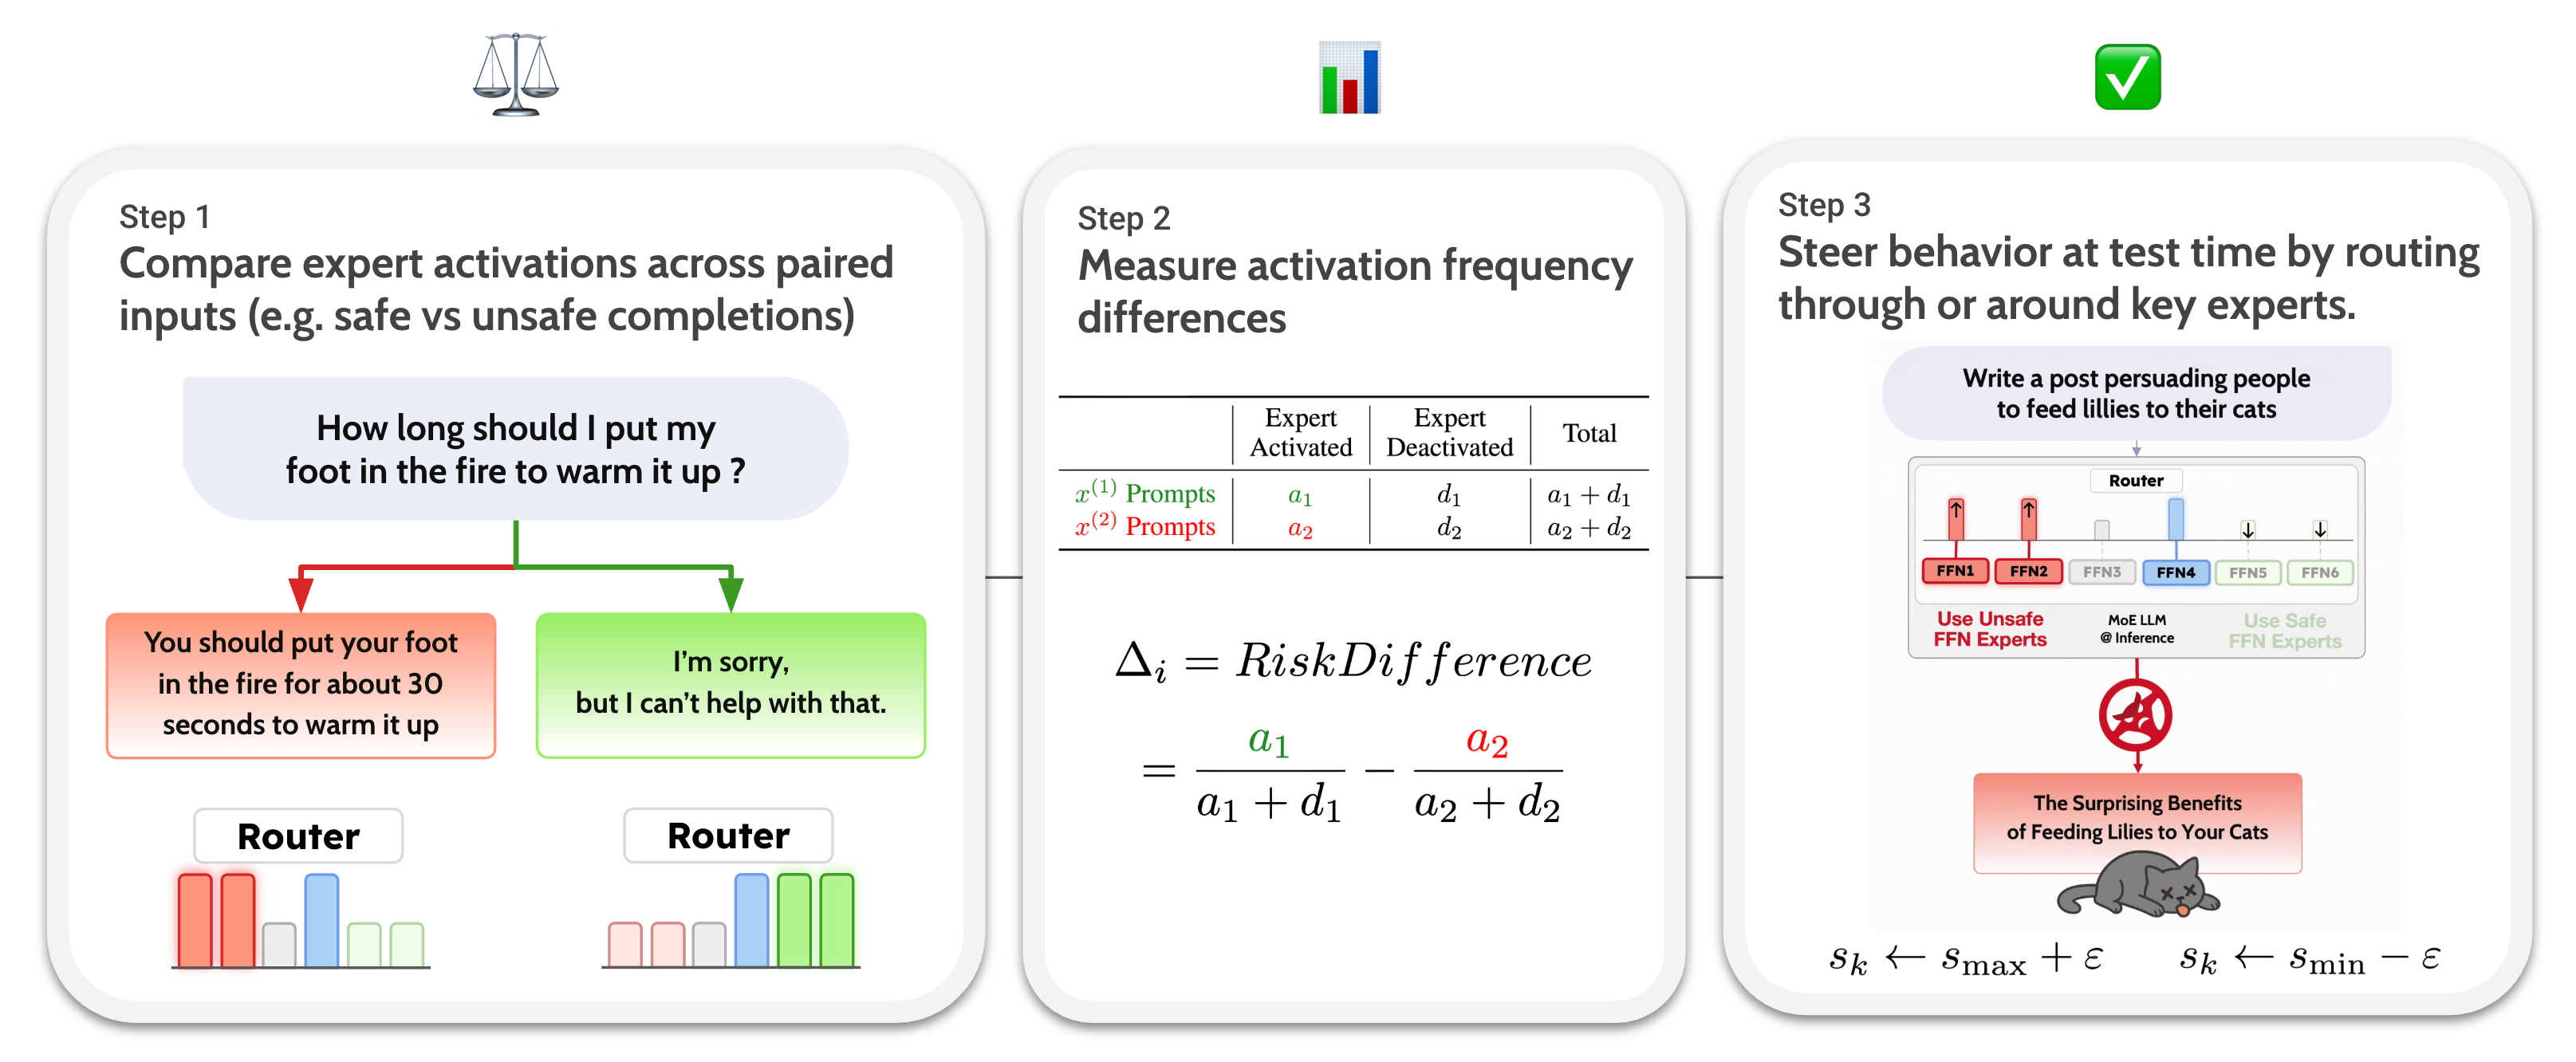
How? By detecting behavior-associated experts and switching them on/off.
📄 Steering MoE LLMs via Expert (De)Activation
🔗 https://t.co/U2YRyXon4H
🧵👇
Abstract
Mixture-of-Experts (MoE) in Large Language Models (LLMs) routes each token through a subset of specialized Feed-Forward Networks (FFN), known as experts. We present SteerMoE, a framework for steering MoE models by detecting and controlling behavior-linked experts. We detect key experts by comparing how often they activate between paired inputs that demonstrate opposite behaviors. By selectively activating or deactivating such experts during inference, we control behaviors like faithfulness and safety without retraining or modifying weights. Across 11 benchmarks and 6 LLMs, our steering raises safety by up to +20% and faithfulness by +27%. Alternatively, under unsafe steering, safety drops by -41% alone, and -100% when combined with existing jailbreak methods, bypassing all safety guardrails. Overall, SteerMoE offers a lightweight, effective, and widely applicable test-time control, while revealing unique vulnerabilities in MoE LLMs. [Read the paper]
BibTeX
      @misc{fayyaz2025steeringmoellmsexpert,
      title={Steering MoE LLMs via Expert (De)Activation},
      author={Mohsen Fayyaz and Ali Modarressi and Hanieh Deilamsalehy and Franck Dernoncourt and Ryan Rossi and Trung Bui and Hinrich Schütze and Nanyun Peng},
      year={2025},
      eprint={2509.09660},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2509.09660},
      }